featured article
Best NPU Laptop for Developers in 2026: Top Picks at Every Budget
Latest articles
Most tutorials assume you have a discrete GPU, but you can run Ollama on ... Read more
⚡ Quick Answer: Install Ollama on Mac with one command: brew install ollama. Then ... Read more
⚡ Quick Answer: To use your NPU on Windows 11, open Task Manager (Ctrl+Shift+Esc) ... Read more
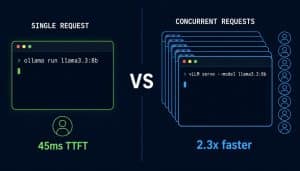
Quick Answer: vLLM is faster than Ollama only above 4–8 concurrent requests. At 1 ... Read more
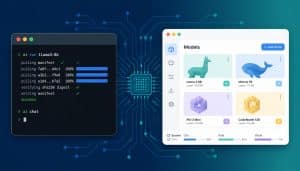
Ollama is faster (10–20%) and built for developers who need an API server, Docker ... Read more
An NPU (Neural Processing Unit) is a dedicated AI chip built into modern laptops ... Read more
⚡ Quick Answer: The best M.2 AI accelerator card for local LLM inference in ... Read more
⚡ Quick Answer: The best local LLM in 2026 is Llama 3.1 8B for ... Read more
You can run a local LLM on low-end hardware with exactly 8GB of RAM ... Read more